 Trial
Requesty
Quick facts
- Pricing model
- Trial
- Minimum price
- Free
- Free access
- Yes
- Regional payment options
- Pay directly on the website
- Service status
- Online, checked
- User rating
Developer and reliability
Information about the developer and the service's terms. This is a factual reference, not a quality assessment or a guarantee of safety.
- Developer
- Requesty
- Legal entity
- Requesty Ltd
- Legal entity's country
- United States
- Registration details
- 15165717
- Service launch
- 2024
- Domain registered
- August 13, 2023
- The domain registration date is not the service's launch date.
Video reviews and tutorials
3Compare with alternatives
Choose a pair to compare features, pricing and assessments.
Editorial assessment
Good productProduction AI infrastructure is notoriously brittle: providers throttle accounts with 429s without warning, latency fluctuates wildly, and billing is scattered across dozens of dashboards. Requesty addresses these operational headaches directly. Having a single gateway that executes sub-14ms failovers, balances traffic between providers, and strips sensitive personal data in real time provides immediate practical value.
We rate Requesty as a Good product. The platform delivers a robust feature set, native integrations for coding tools, and clear data residency options for European teams. However, it remains a young, venture-backed startup with a compact team, its SOC 2 Type II certification is still in progress, and teams looking for an open-source, self-hosted proxy will have to look elsewhere. But if you want a turnkey managed proxy that tames multi-provider chaos without rewriting your codebase, Requesty performs reliably.
- Functionality Good
- Price and value Good
- Ease of use Good
- Reliability and support Average
- Innovation Good
About the tool
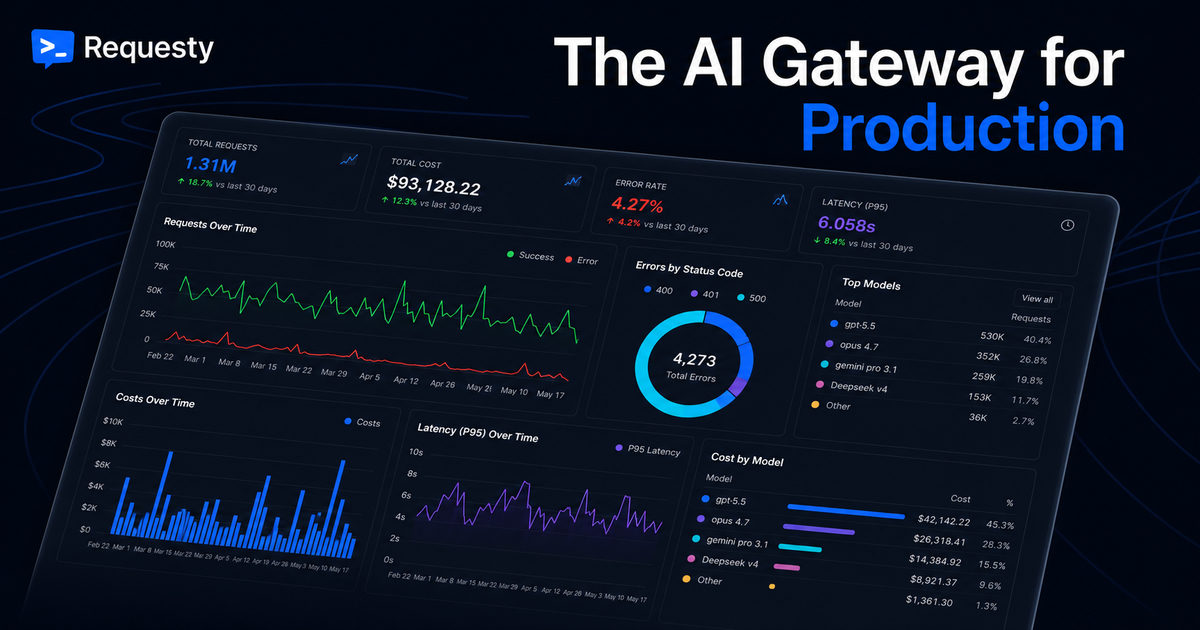
Requesty is a high-performance AI gateway and LLM proxy that sits between your applications and hundreds of external model endpoints. Instead of hardcoding vendor-specific client libraries and hoping their servers never crash, you route every call through a single OpenAI-compatible endpoint and let Requesty handle the infrastructure headaches.
The platform handles the heavy lifting of production AI operations:
- Drop-in integration: Switch your API endpoint with a single base URL change in your existing OpenAI SDK setup. No refactoring or proprietary vendor lock-in.
- Intelligent multi-model routing: Configure automated failover chains that intercept 429 rate limits and 5xx upstream failures in under 14 milliseconds, route traffic dynamically based on real-time latency and generation speed, or split workloads across models with weighted load balancing.
- Agent routing policies: Assign specific fallback chains, spending limits, and model tiers to autonomous agents, ensuring heavy reasoning tasks reach powerful models while routine batch operations stay on low-cost options.
- Real-time privacy and guardrails: Built-in scanners detect and scrub personal identifiable information (PII) such as emails, phone numbers, and payment cards in roughly 3 milliseconds before prompts leave the gateway, backed by prompt-injection filters.
- Regional sovereignty: Dedicated gateways in the European Union (Frankfurt on AWS), the United States, and Asia-Pacific allow teams to enforce strict data residency rules and pin traffic to zero-retention endpoints.
- Observability and cost control: Detailed dashboards break down spending, token consumption, and latency regressions by team, user, API key, and agent, paired with prompt and semantic caching to prevent paying twice for identical queries.
How it helps you
Requesty helps engineering teams build resilient, production-ready AI workflows without getting derailed by provider outages, unexpected bill spikes, or data compliance hurdles.
- Platform and backend engineers gain automated failovers, zero-downtime provider switching, and unified latency monitoring across all providers.
- Regulated organizations in LegalTech, FinTech, and healthcare can guarantee strict European data residency, sign standard DPAs, and redact sensitive PII automatically.
- Autonomous agent builders can enforce strict per-agent spending caps, route requests to role-appropriate models, and debug tool calls without wrangling multiple SDKs.
Pros and cons
Pros
- Drop-in OpenAI SDK compatibility allows switching models or routing chains with a single configuration line
- Automated sub-14ms failover absorbs 429 rate limits and upstream outages without breaking user sessions
- Comprehensive routing options including live latency scoring, percentage-based load balancing, and agent-specific chains
- Real-time PII detection and redaction strips personal data before prompts reach upstream providers
- Strict regional data residency options with dedicated EU infrastructure and zero data retention endpoints
- Transparent billing with a 5% markup on pay-as-you-go, 0% markup when bringing your own keys (BYOK), and a free tier
Cons
- Proprietary SaaS platform with no option for self-hosted or fully air-gapped on-premise deployment
- Adds a proxy network overhead of roughly 12 to 40 ms to raw inference calls
- Free-tier endpoints have strict daily request caps and are subject to provider queue congestion
Category partner
 Polza.ai ▲ 5 ▼ 1
Connecting dozens of foreign AI platforms, juggling credit cards that get declined, and setting up proxy servers just to query an LLM is a massive waste of engineering time.
User reviews
No reviews collected yet
We are collecting user reviews of this tool from public sources. They will appear here soon.
Pricing
FREE
PAY AS YOU GO
ENTERPRISE
Prices are based on the provider's information and may change.
Looking for a free option? Try these alternatives to Requesty:

Compare with popular alternatives
Compare key features, prices and capabilities with similar tools
| Feature | Current tool |  |  | |
|---|---|---|---|---|
| Pricing model | Trial | Pay as you go | Pay as you go | Pay as you go |
| Minimum price | Free | Pay as you go | Pay as you go | Pay as you go |
| Free access | Yes | No | No | No |
| Regional payment options | Direct payment | Direct payment | Direct payment | Direct payment |
| Editorial assessment | Good product | Good product | Good specialized service | Good specialized service |
| User rating | ||||
| Current tool |
Frequently asked questions
How do you integrate Requesty into an existing codebase?
Integration requires only modifying the base URL and API key in your standard OpenAI SDK client for Python or Node.js. Point your configuration to router.requesty.ai and specify either a model name or a predefined routing policy. Your existing request schemas and prompt templates remain unchanged.
Can I bring my own provider API keys?
Yes. Requesty fully supports a Bring Your Own Keys (BYOK) setup. When using your own keys for providers such as OpenAI, Anthropic Claude, or Google Gemini, Requesty applies a 0% markup. You pay your contracted provider rates directly while still accessing Requesty’s routing, caching, and observability.
How does Requesty handle European data residency?
Requesty maintains a dedicated European gateway hosted in Frankfurt on AWS (router.eu.requesty.ai). Pointing requests to this endpoint ensures data processing remains strictly within the EU, supported by GDPR Article 28 Data Processing Agreements and eligible zero data retention endpoints.
What happens when an upstream model provider experiences an outage?
If an upstream provider returns a 429 rate limit or a 5xx server error, Requesty's automated failover intercepts the error and forwards the request to the next configured fallback model in under 14 milliseconds, returning the response seamlessly to the caller.
Similar tools
 VseLLM ▲ 3 ▼ 0
VseLLM is an infrastructure API gateway and aggregator that delivers unified access to major international AI models through an OpenAI-compatible endpoint.
 provod.ai ▲ 5 ▼ 0
provod.ai is an infrastructure gateway and workspace that brings together major international and open-source generative models under a single account, a unified ruble balance, and dual-protocol API access.
 AITUNNEL ▲ 4 ▼ 0
AITUNNEL is an infrastructure gateway that provides unified access to over two hundred AI models through a single API endpoint.
 BotHub ▲ 4 ▼ 0
BotHub is a multimodal AI aggregator and unified API gateway designed to eliminate the friction of managing dozens of individual neural network accounts.
 NeuroAPI ▲ 3 ▼ 0
NeuroAPI is an infrastructure API gateway designed to give engineering teams and businesses unified access to leading artificial intelligence models under a single account and balance, with billing in rubles and no need for foreign payment methods or network proxies.